Case Study 06 · Full-Stack · Completed
Django Blog
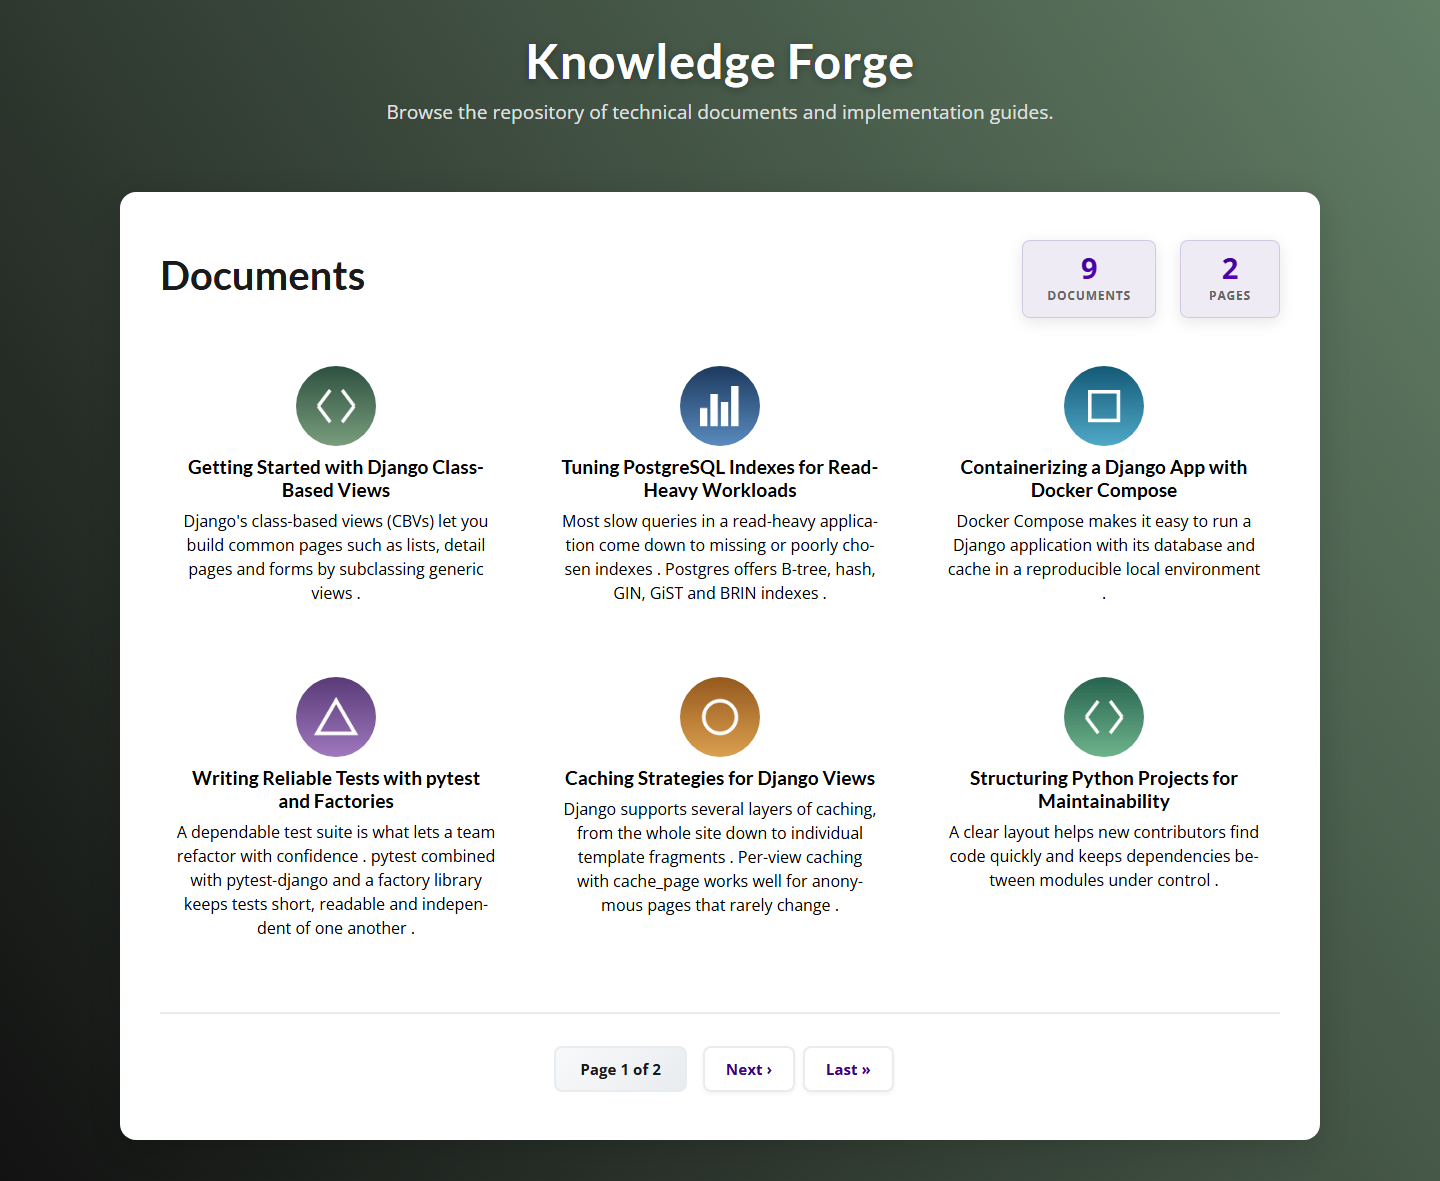
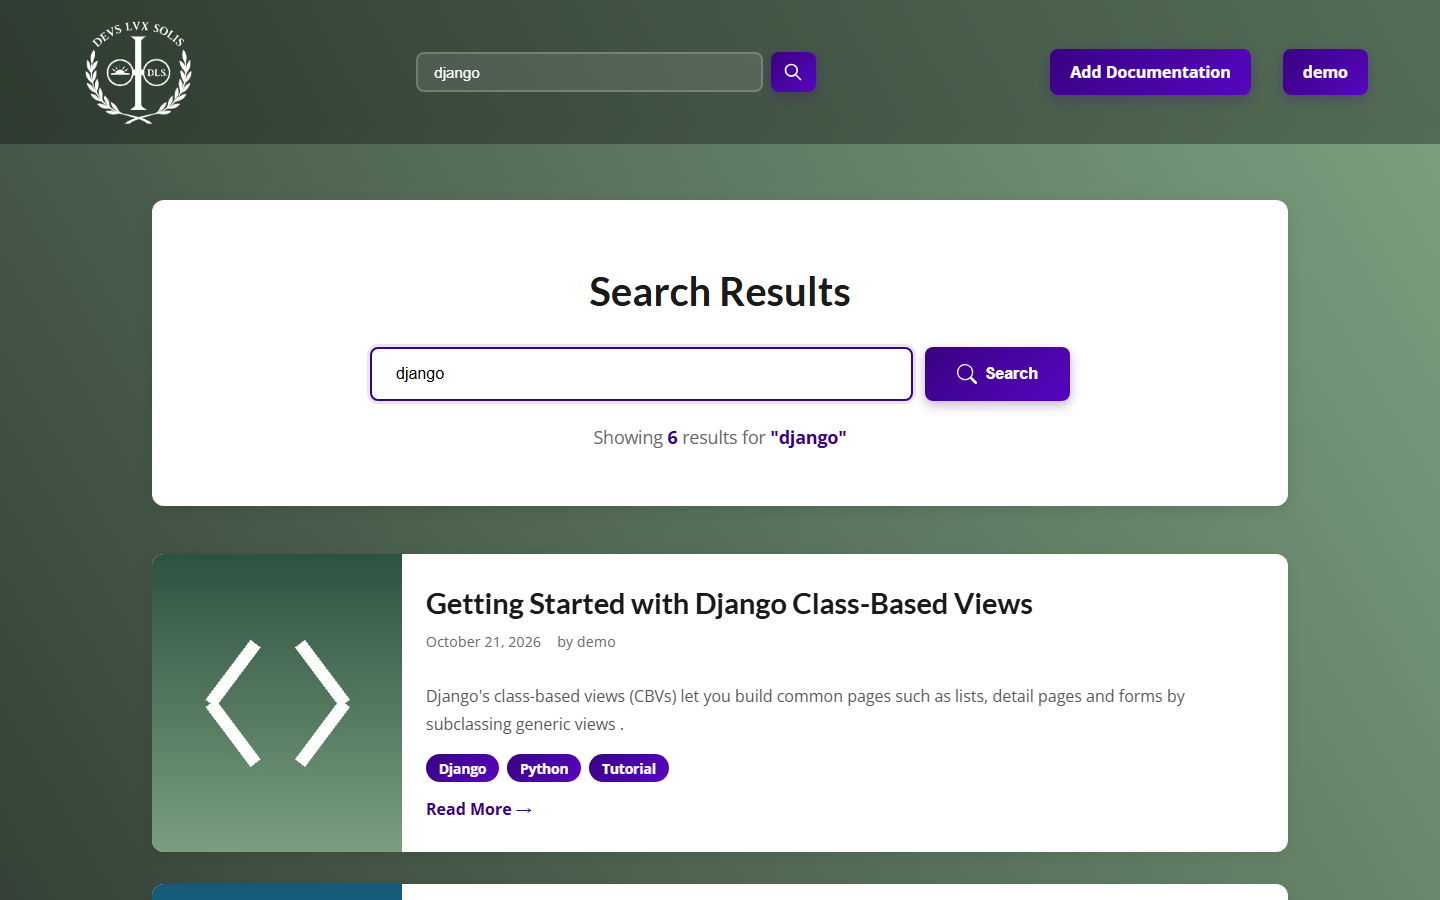
A Django blog with rich-text and PDF posts, tags and search. Post excerpts come from a summarization model that runs locally with PyTorch and Hugging Face.
Problem
I wanted one place to keep and re-find technical notes, including PDFs. Writing an excerpt for every post by hand is the step that gets skipped, and without excerpts the post list is hard to scan.
Solution
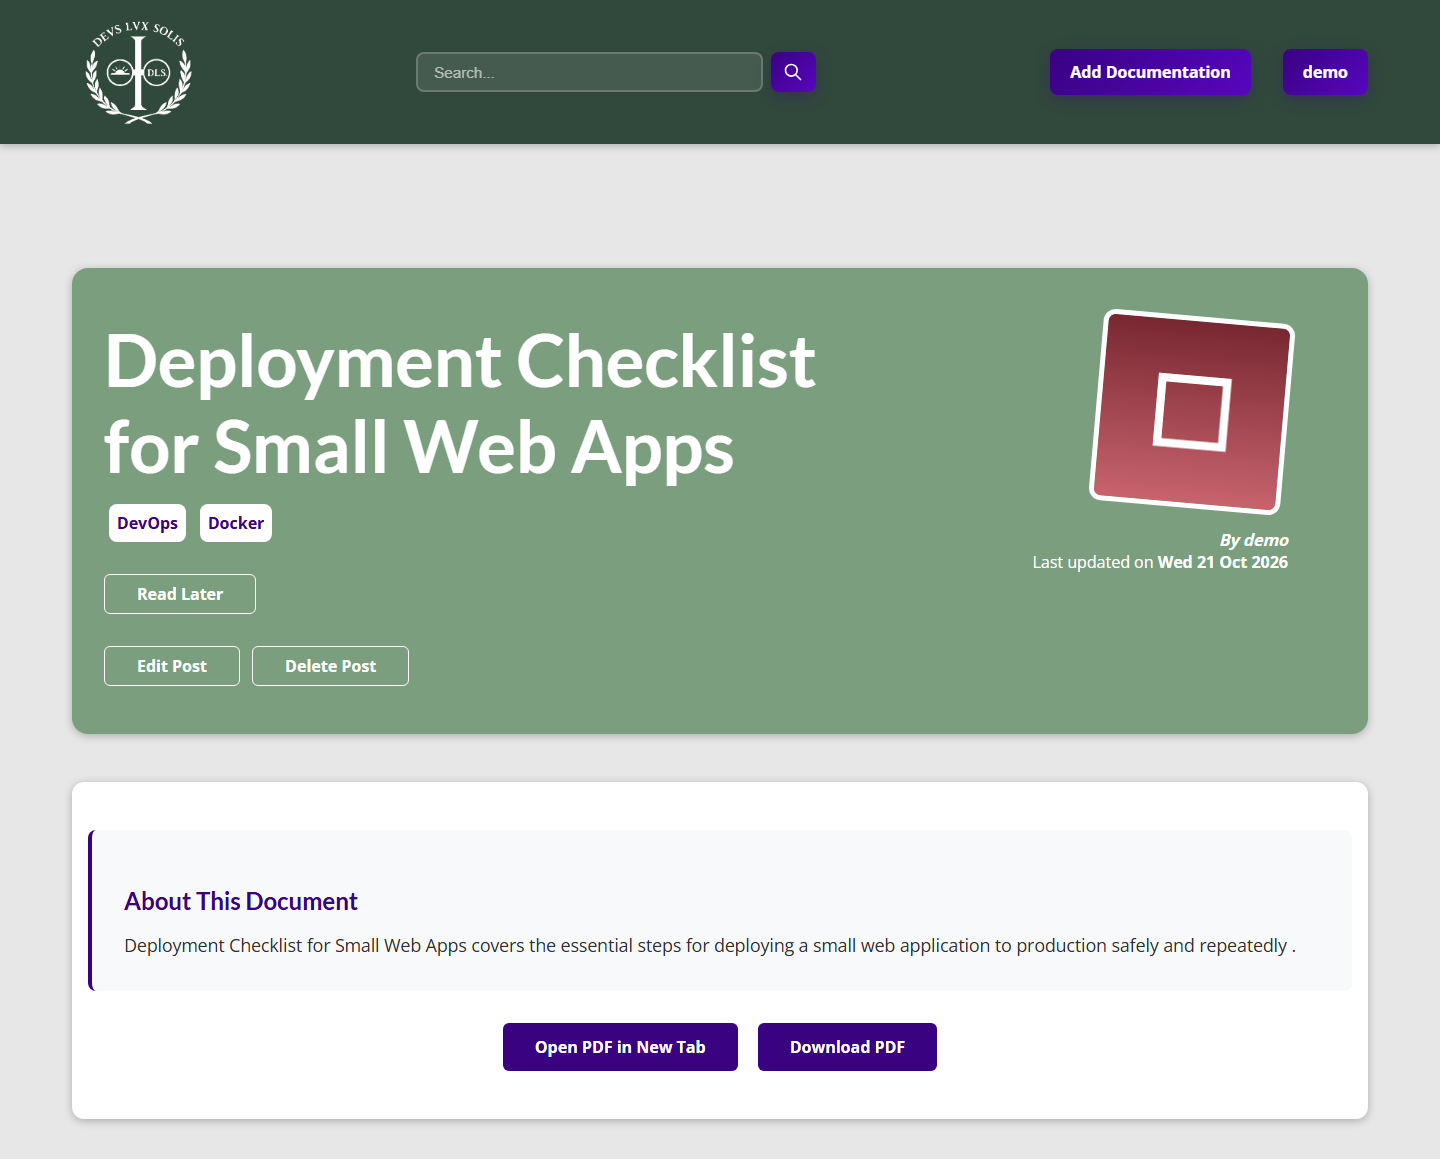
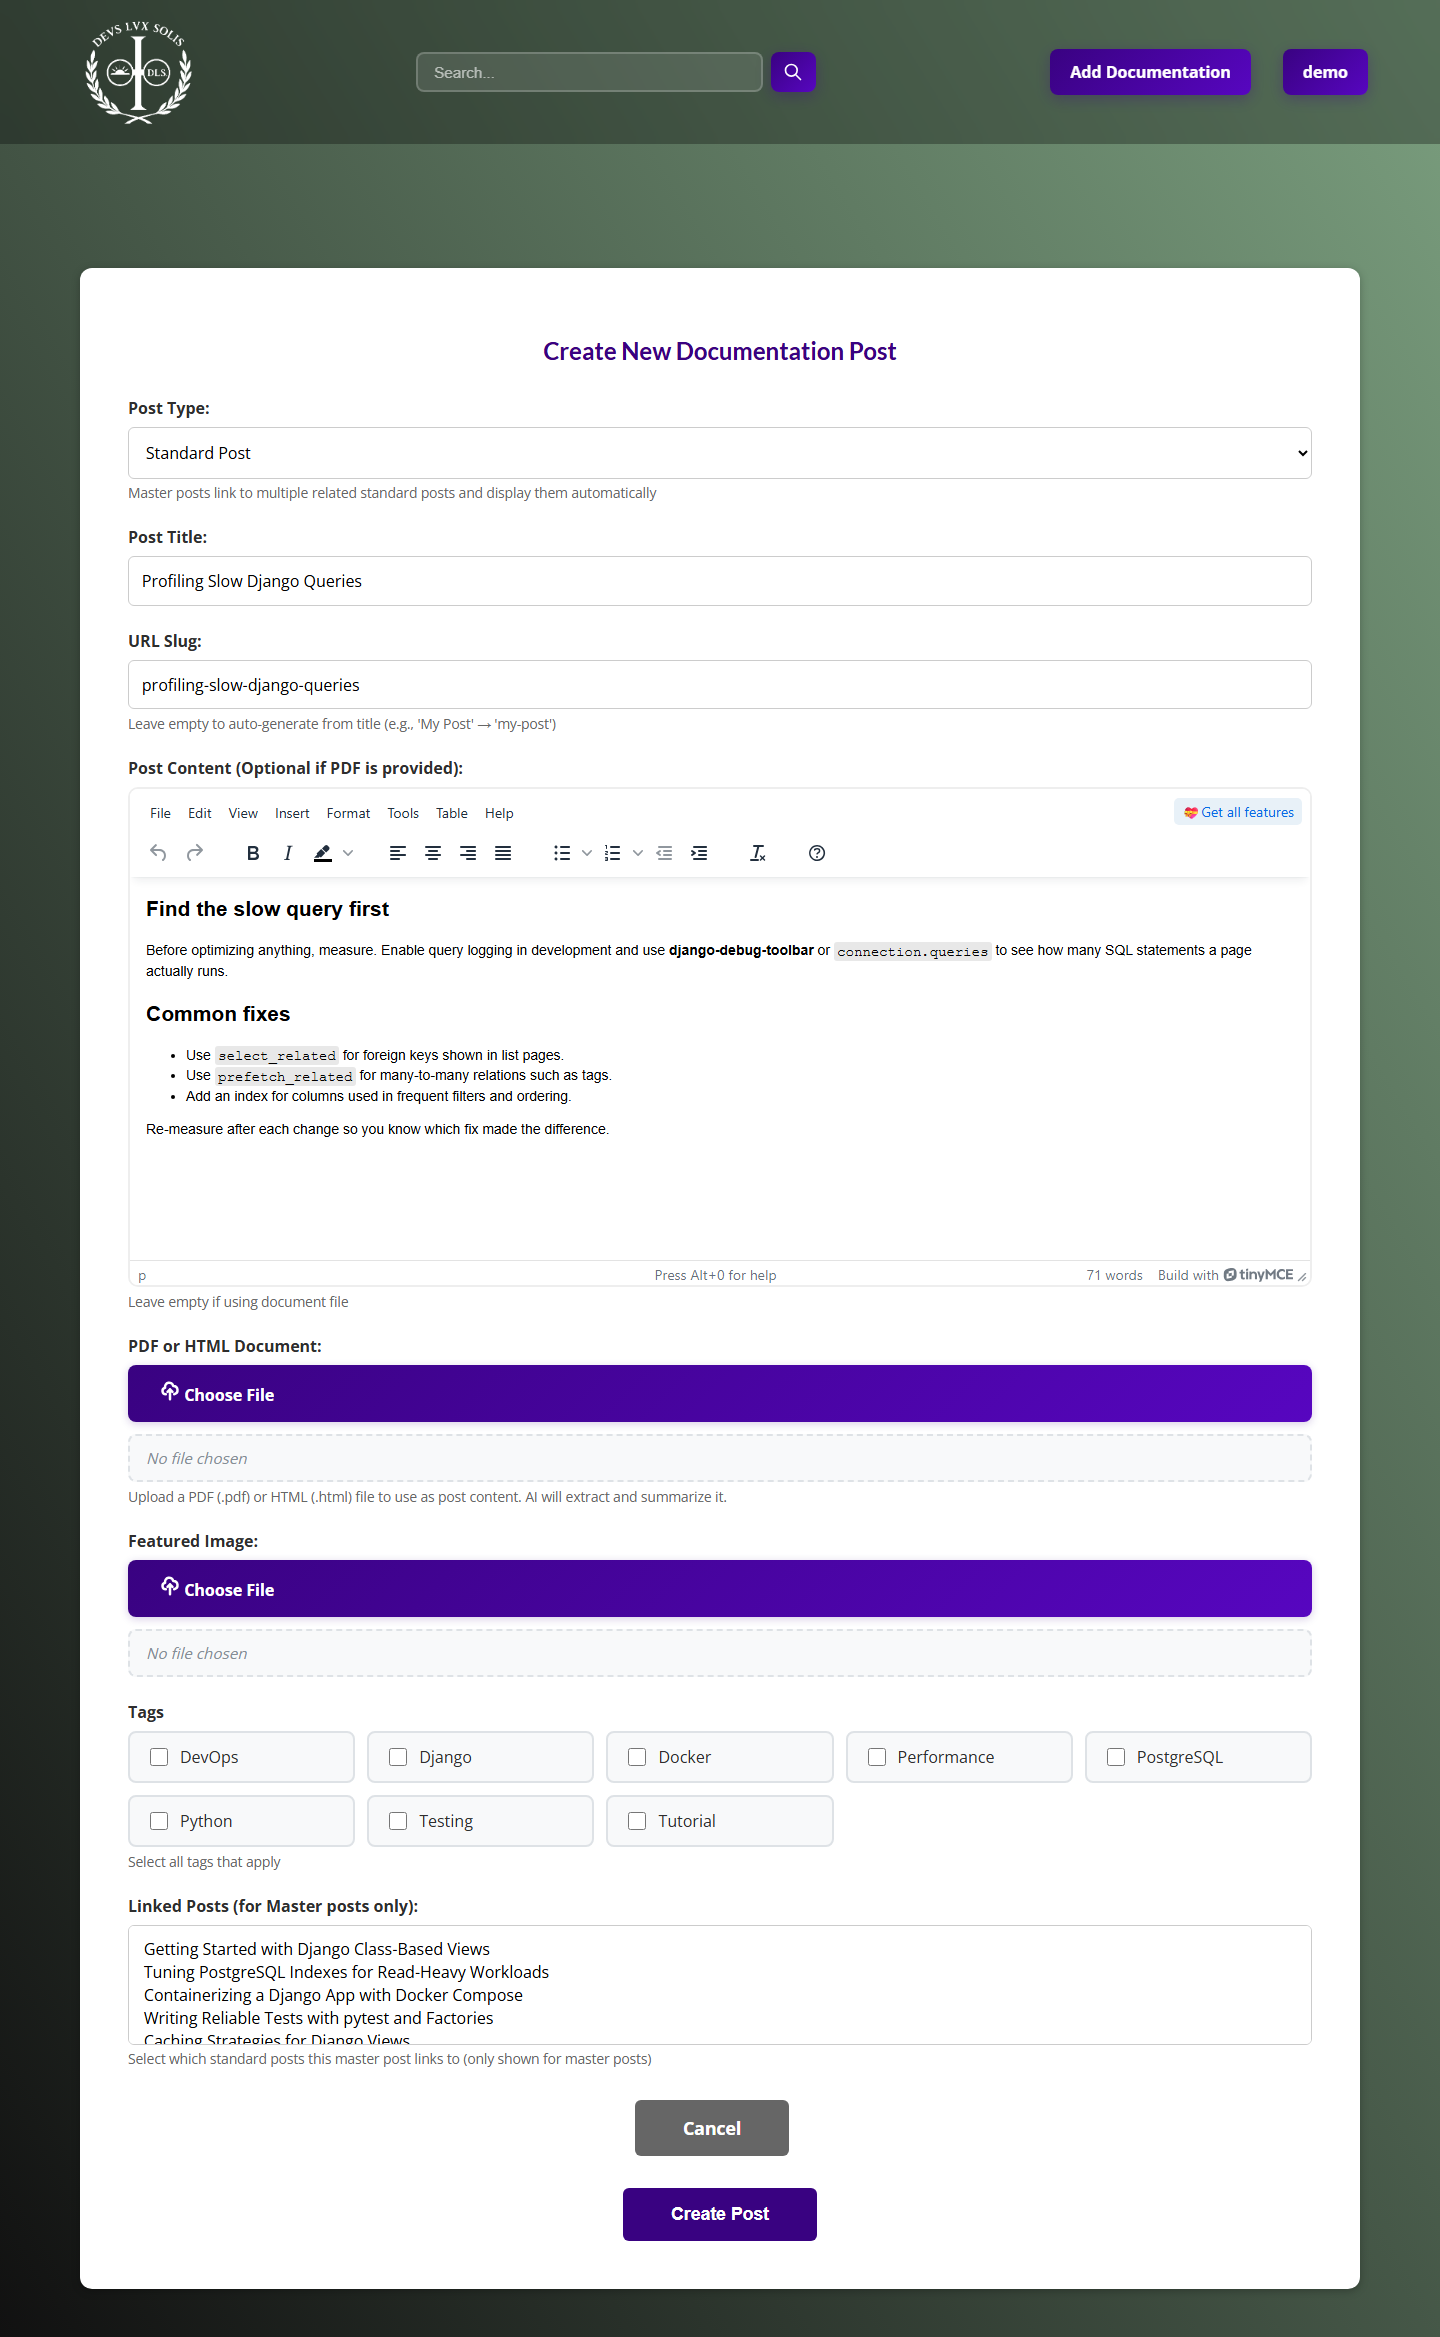
A Django app with TinyMCE authoring, PDF upload, tags, full-text search, profiles and per-user comments. Excerpts are written automatically by a local summarization model, DistilBART through Hugging Face transformers on PyTorch, from either the post body or the uploaded PDF's text.
Highlights
- The summarizer is a singleton, so the model loads once per process instead of once per request.
- A distilled DistilBART checkpoint was chosen on purpose, trading a little quality for speed and memory.
- Device selection is automatic: GPU when one is available, CPU otherwise, on the same code path.
- PDF text is extracted with PyPDF2, so uploaded documents get excerpts too.
- Comments pass through a profanity filter, and tags drive front-end filtering alongside search.
Outcome
Every post gets an excerpt with no extra work, and the model runs on the same machine as the app, with or without a GPU. Search and tag filtering make older notes easy to find again.
How the Work Ran
A solo project, built in small feature steps, with a later pass on speed and homepage caching.
Tech
- Hugging Face Transformers
- PyTorch
- Django
- Python
- Tailwind